Technology Insights
Why Does AI Adoption Fail? 5 Failure Patterns and How to Recover
Most enterprise AI adoption failures are not technical problems: the demo trap, unprepared data, no business owner, the wrong first use case, and no acceptance criteria. Drawing on rescue projects, this article sets out the five failure patterns and how to address each one.
Contents
When enterprise AI adoption fails, it is often not because the model's answers are not smart enough, but because the project never had a clear operational use case, data ownership, or way of accepting the results. Switching models may make the demo look better, but it will not fix permissions, processes, or organizational problems on its own.
The five patterns below come from rescue situations that recur across enterprise projects. The cases have been generalised and do not refer to any specific client. If you are choosing a partner, you may want to start with our 2026 guide to choosing an AI adoption company.
Why does an impressive AI demo fail to make it into the real workflow?
A demo usually validates a single scenario, while a production workflow also has to handle permissions, exceptions, integration, and accountability. If the operating conditions are not defined from the start, a good demo cannot be turned directly into something that goes live.
What usually happens
The team builds a polished Q&A on a small set of hand-picked documents, and management approves the demo. Only when preparing to go live does it become clear that there is no login or permission model, no data updates, no source citations, no monitoring, no cost ceiling, and no human takeover.
Warning signs
- Test data is curated by hand by the project team and is not connected to the official sources.
- Only successful questions are shown; there are no failures, unanswerable questions, or out-of-permission cases.
- There are no real users, no incident contact, and no one accountable for the launch.
Prevention and rescue
Write the go-live checklist before the PoC: users, data sources, permissions, integration, risks, monitoring, and acceptance. The demo can stay small, but architectural decisions must know how the system will reach the real environment.
How does unprepared data make AI projects fail?
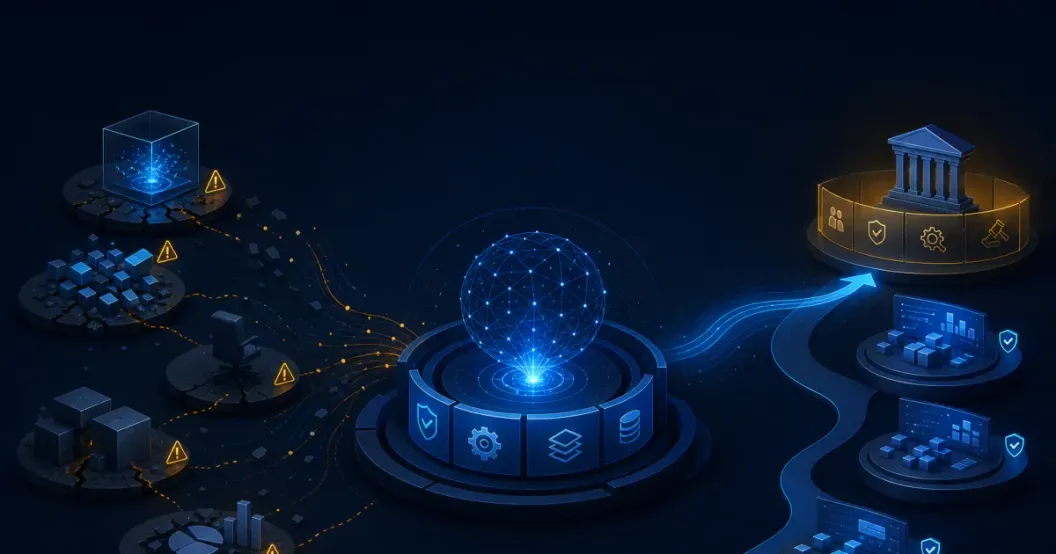
AI amplifies the gaps, contradictions, and permission problems already present in your data. Establishing rules for data sources, quality, and ownership first usually does more for the results than switching models.
What usually happens
Different departments hold contradictory versions of documents, categories are inconsistent, and permissions and retention periods are unclear, yet AI is expected to sort it all out into a single answer. Once users run into wrong answers, they quickly lose trust.
Warning signs
- No one can say which system or document is the official source.
- No one is responsible for updating content or retiring outdated material.
- When a test fails, the only fix available is changing the prompt, because the problem cannot be traced back to a data source.
Prevention and rescue
Pick one data domain and define its owner, versioning, permissions, and update rules; build a minimum viable dataset and a fixed set of test questions. Data governance does not have to cover the whole company at once, but it must be accountable for the current use case.
Failure pattern 3: No business owner
What usually happens
The AI project is handed to IT or an innovation team, and the business only gives feedback at demos. No one can decide how exceptions are handled, how much error is tolerable, whether the content is correct, or how the system will be used after launch.
Warning signs
- Meetings have plenty of stakeholders but no final decision-maker.
- The technical team is asked to work out business rules on its own.
- After launch, no one tracks adoption, feedback, or content improvements.
Prevention and rescue
Appoint a business owner with real authority who is accountable for the use case, the data, and the results; IT is responsible for architecture, security, and operational capability. Decisions, data, models, and systems each need a clear owner.
Failure pattern 4: The first use case is too large
What usually happens
The first phase is expected to deliver a company-wide knowledge platform, automated customer service, sales recommendations, and operational analytics, in the hope of proving AI's strategic value in one go. Every department has different rules, and in the end nothing can be fully accepted.
Warning signs
- Requirements are described as "all documents", "all employees", or "any question".
- Permissions, data, and integration span several units that have not yet aligned.
- The project has no first milestone that can go live on its own.
Prevention and rescue
Narrow it down to one group of users, one type of question, one data domain, and one work outcome. The first use case should be able to fail safely, be reviewed by people, and build up real evidence within a short cycle.
What happens to an AI project without a baseline or acceptance criteria?
Without a baseline of the current state, you cannot prove whether AI has brought any improvement; without acceptance criteria, you cannot decide when to go live. The project then tends to stall in subjective opinions and endless adjustment.
What usually happens
The team only asks whether the AI's answers "look good". No one has measured how long the original process takes or where it goes wrong, and there is no fixed test set. After every model or prompt update, quality can only be argued about from impressions.
Warning signs
- There is no pre-adoption data on time, cost, errors, or usage.
- The test questions change every time, so versions cannot be compared.
- Only accuracy is measured; human takeover, permissions, security, and cost per run are not.
Prevention and rescue
Establish a current-state baseline before development, and break success down into task completion, quality, time, human effort, risk, cost, and adoption. Build an evaluation set that can be rerun, and add acceptance testing on the real process.
Five steps to rescue an AI project
JoinX's rescue experience shows that the first step is not to swap the model straight away, but to reconfirm the goals, the current state, and who is responsible. Only by first finding which layer the failure occurred in do later adjustments have a basis that can be accepted.
1. Redefine the scope
Rewrite "adopt AI" as a specific outcome to improve for specific users in a specific process, and list the data and actions that are out of scope.
2. Build minimum viable data
Choose a dataset that is sufficient to validate the use case and whose permissions and versions can be confirmed. Keep rules for sources, updates, and expiry, rather than trying to collect all content at the start.
3. Add an engineering baseline
Set up environments, versioning, permissions, logging, monitoring, testing, cost controls, and human takeover, so every change can be traced and failures can stop safely.
4. Rebuild measurement
Compare before and after in the same way, and build a fixed test set. Beyond answer quality, also test process completion, permission blocks, exception recovery, and operating cost.
5. Roll out gradually
Start with a small number of real users working under human review, and expand step by step based on the types of errors and how people actually use it. Each expansion should have clear entry and stop conditions.
Do not use a new model to cover up old problems
Model capabilities will keep improving, but the following problems will not disappear with an upgrade:
- The data has no owner.
- User permissions are unclear.
- The process itself is contradictory.
- The system cannot be monitored or rolled back.
- The organization has no mechanism for decisions or continuous improvement.
Put these foundations in place first and then compare models; only then will you know where the improvement came from. For the full set of adoption phases, see our 2026 guide to enterprise AI adoption services; for technology choices, read on in enterprise AI, generative AI, RAG, and agents explained.
Conclusion: Turn failure into a next step you can verify
A project that is already stuck does not have to be thrown away entirely. First work out whether the problem lies in the use case, the data, ownership, engineering, or acceptance; keep the interviews, test data, interfaces, and integration work that are still usable; then rebuild the evidence with a smaller scope.
The goal of a rescue is not to declare success at any cost, but to give the company its options back: to know whether to continue, adjust, or pause, and under what conditions to expand.
Frequently Asked Questions About AI Adoption Failure
What is the most common reason AI adoption fails?
The usual causes are the demo trap, unprepared data, no business owner, a use case that is too large, and no acceptance baseline.
Why can't a successful AI demo go straight into production?
A production system also has to handle permissions, integration, monitoring, exceptions, cost, security, and ongoing updates.
Can we still do AI if our data is a mess?
You can start validating with a small, controllable dataset, but you must set up ownership, versioning, and permissions at the same time.
Should the IT department own the AI project?
IT is responsible for technical governance, but the business still needs to appoint an owner who can decide the process and the results.
How should we choose the first AI use case?
Choose a process that is high-frequency and clearly bounded, where the data is available, the results can be verified, and errors are containable.
How should an AI rollout be accepted?
First establish a current-state baseline, then measure tasks, quality, time, human effort, permissions, cost, and adoption.
Does a failed AI project have to be rebuilt from scratch?
Not necessarily. You can keep the assets that work, narrow the scope, and rebuild the data, engineering, and acceptance baselines.
How does JoinX help rescue AI projects?
JoinX first diagnoses the use case, data, systems, and governance, then restructures the project around minimum viable data, an engineering baseline, and a phased rollout.
About the author
Jack Lee
Founder & CEO, JoinX
Jack founded JoinX in 2016 and leads a team of 80+ people across Taiwan and Japan. JoinX has delivered 520+ projects for 220+ clients, including 56 mid-to-large systems.
More about Jack